Multi-Model Consensus: Agreement Is a Signal, Not Proof
How to use model disagreement for review, test correlated errors, and decide whether an extra model earns its cost. A practical architecture with clear limits.
Ostap Kovalisko
Founder & AI Systems Architect
Updated 2026-10-18 · Sources and technical review
In this article · 6 min
Three models give you the same answer. It feels reassuring. Then you open the document they all used and discover that the document is out of date. The agreement was real. So was the mistake.
That is the distinction I want a review system to preserve. Asking more models can expose uncertainty, but counting votes cannot establish whether a claim is true. The useful product is a better inspection path: show the conflicting claims, show the evidence, and make it easy to check what matters.
Separate agreement from evidence
A practical comparison starts with independently produced answers. Keep the original outputs before asking a synthesis model to summarize them. Otherwise a fluent summary can erase the very disagreement you wanted to inspect. Compare individual claims, values and citations rather than asking whether the answers sound similar.
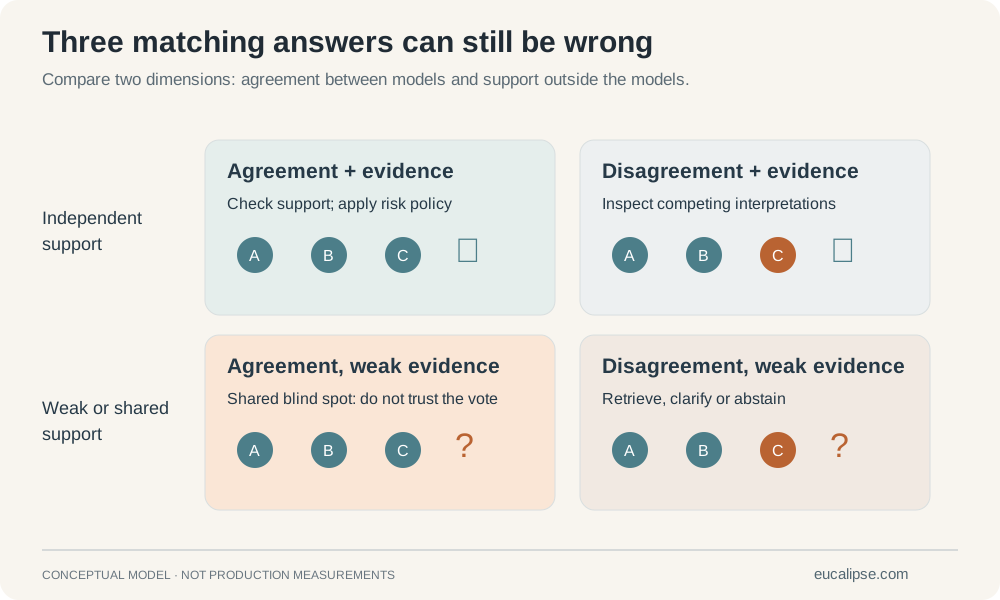
Agreement and independent support belong in separate fields. Three answers quoting the same page are three interpretations of one source. A verifier executing a calculation or checking a database record adds a different kind of evidence. Its result still needs to be relevant to the claim.
What the research does—and does not—establish
Du and colleagues investigated multiagent debate and reported improvements on the tasks in their experiments. That is a reason to test the technique, not a guarantee that three chosen providers will improve your own workflow. Their paper on multiagent debate is a useful starting point for designing that comparison.
Anthropic’s workflow guide also describes parallel voting as a pattern. Neither a pattern diagram nor a benchmark replaces evaluation on the errors your application actually makes.
Build a comparison that can fail honestly
- Run a single-model baseline and the ensemble on the same held-out cases. Keep difficult cases and ordinary traffic in the sample.
- Score correctness against independently established answers. Do not use the majority vote as its own ground truth.
- Count unanimous wrong answers separately. These are the cases a disagreement-only detector will miss.
- Measure false alarms too. A system that sends everything to review can detect errors while creating an unusable queue.
- Include provider failures, missing answers, synthesis calls, retries and review time in the cost comparison.
Choose a policy before choosing a third model
For a low-impact summary, a disagreement may justify a caveat. For an action that changes a customer record, unresolved conflicting values should stop execution. The policy depends on the consequence, the available evidence and the recovery path. It should not quietly change because two models outvoted the third.
Do not silently drop a failed model and call the remaining result unanimous. Record which participants answered and which evidence was available. If one provider changes its model or retrieval changes, evaluate the resulting system again.
I would start with the narrowest expensive mistake we can describe. If a second independent check catches that mistake at an acceptable review cost, keep it. If it mainly repeats the first answer, spend the budget on better retrieval, a deterministic validator or a clearer review screen instead.
Connect the result to the reviewer
A useful card shows the disputed field, the alternatives and the source passages. It does not ask a person to compare three essays. The same idea runs through Every value needs a source: a value becomes easier to review when its origin remains visible.
This article describes a design and an evaluation method. It does not claim a measured accuracy improvement for an Eucalipse deployment.
Frequently asked questions
Does agreement between models prove an answer is correct?+
No. Models can agree on the same unsupported claim. Verify important claims against independent evidence and evaluate unanimous errors.
When is an ensemble worth its cost?+
When a controlled comparison on relevant cases shows useful improvements after accounting for extra inference, latency, retries and human review.
Let's Talk About Your Project
Have questions about nearshoring or AI development? Our team is here to help you make the right decision.
- ✓Free consultation on your AI project
- ✓Custom cost estimates and timeline
- ✓Access to nearshore talent pools