LLM Cost Optimization: Measure the Whole Workflow
A practical guide to routing, caching and retries, with an interactive cost model. Compare cost per successful task instead of promising universal savings.
Ostap Kovalisko
Founder & AI Systems Architect
Updated 2026-10-18 · Sources and technical review
In this article · 6 min
A cheap model call can be an expensive decision. It becomes expensive when it sends a request down the wrong path, needs three retries, or leaves somebody repairing the answer. The invoice sees tokens. Your team experiences the whole task.
I would start a cost review with one question: what does it cost to finish this task correctly? A routing change is useful when that number improves without hiding a quality loss. A lower average price per call is not enough.
Make the assumptions visible
The calculator below is deliberately small. It compares a premium-only baseline with a routed workload. Prices are abstract cost units, not current provider prices. You can change the share handled by a smaller model, its relative call cost and the extra attempts caused by the routed workflow.
Example: 534 cost units versus a 1000-unit baseline (46.6% lower).
Illustrative example. Toy model: 1,000 equal-size requests; premium call = 1 unit; router = 0.05 unit/request. Extra attempts use the same model mix. No provider prices, cache discounts, quality benefits, latency or measured savings are implied.
View data table
| Category | Base calls | Extra attempts | Router overhead |
|---|---|---|---|
| Premium-only baseline | 1000 | 0 | 0 |
| Routed workload | 440.00000000000006 | 44.00000000000004 | 50 |
At the default settings, 700 small calls cost 140 units and 300 premium calls cost 300. Extra attempts add 44; the router adds 50. The total is 534 units against a 1,000-unit baseline. That is arithmetic under stated assumptions, not a production savings claim. It says nothing about whether the answers are good enough.
Price successful tasks, including repair
Record model, input and output tokens, cache usage, tool charges and retries against a task identifier. Track failures and abandoned tasks alongside successes. If you calculate cost per successful task, include the money spent on unsuccessful attempts in the numerator; otherwise the hardest failures disappear from the bill.
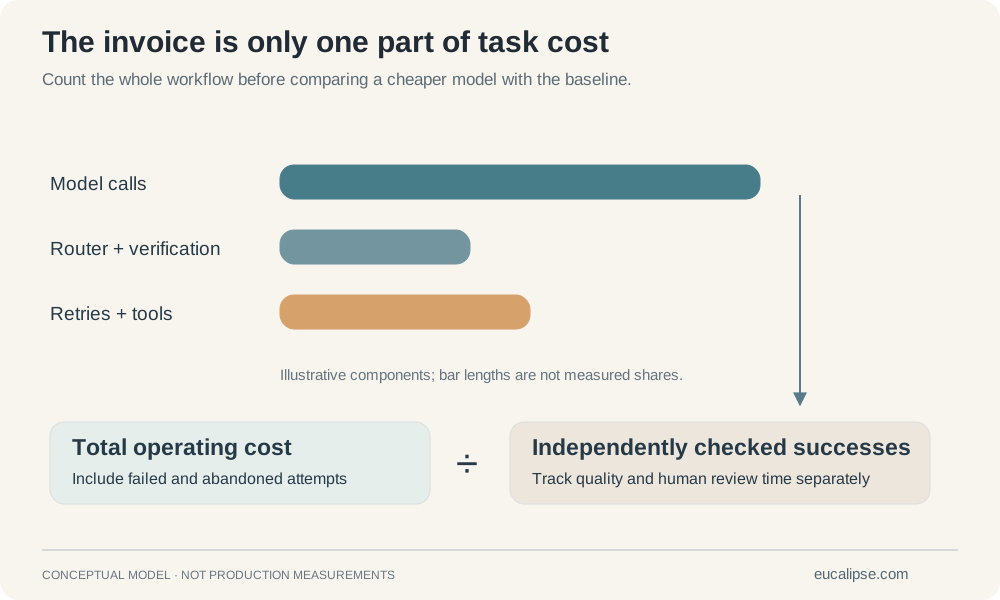
Human repair deserves its own line. If reviewers spend longer correcting the cheaper model, the change may simply move cost out of the API account. Keep monetary costs and review minutes separate until you have an explicit rate and a defensible conversion.
Route on evaluated capability
A narrow output format does not automatically make a task easy. Extracting one date from conflicting documents can be harder than writing a long summary. Evaluate candidate models on representative cases, including missing values, conflicting sources and unexpected inputs. Escalate when checks fail, and record the cost of escalation.
The experimental loop in Evals that grow themselves is a better companion to a cost chart than a universal percentage target. You need evidence that the revised workflow still does the job.
Keep different kinds of caching separate
Prompt caching reuses supported prompt prefixes under a provider’s rules. Application response caching reuses an answer and therefore needs its own freshness, authorization and invalidation policy. A cache hit on a private answer must never cross the access boundary between users.
Anthropic’s prompt-caching documentation explains cache writes, reads and lifetime rules. Estimate savings using the actual hit rate and applicable pricing. Do not assume every repeated-looking request receives a discount.
Bound the expensive paths
Give each workflow an attempt limit, an output budget and a stopping condition. Track the expensive path separately: synthesis, external search and repair can dominate the initial generation call. A timeout should not automatically start the same costly work again if the first attempt may still be running.
Compare before and after on the same workload and report quality, latency and total cost together. A routing policy can save money, cost more, or change nothing useful. The point of the model is to expose those possibilities before the invoice does.
Frequently asked questions
Does routing guarantee lower cost?+
No. Router overhead, retries, escalations and review work can outweigh cheaper calls. Compare total cost and quality on the same workload.
Are the calculator values provider prices?+
No. They are explicitly illustrative cost units. Replace the assumptions with measured usage and dated prices before making a purchasing decision.
Is prompt caching the same as caching an answer?+
No. Provider prompt caching reuses eligible input prefixes. Answer caching reuses an application result and requires freshness and access-control rules.
Let's Talk About Your Project
Have questions about nearshoring or AI development? Our team is here to help you make the right decision.
- ✓Free consultation on your AI project
- ✓Custom cost estimates and timeline
- ✓Access to nearshore talent pools