Confidence Scoring: Test the Number Before Trusting It
Separate model scores, empirical calibration and permission to act. Use reliability diagrams and held-out evaluation instead of decorative confidence percentages.
Ostap Kovalisko
Founder & AI Systems Architect
Updated 2026-10-18 · Sources and technical review
In this article · 6 min
A number beside an answer changes how the answer feels. “92% confidence” looks measured, even when it is just another string the model generated. Before putting that number in a review screen, I want to know what it predicts and how we checked it.
Is it confidence that the request belongs to a category? That a field was extracted correctly? That an entire action will finish safely? Those are different events. One score cannot quietly stand in for all three.
Define the event and the label
Start with a checkable outcome: for example, whether a proposed supplier identifier matches the independently adjudicated identifier. Specify what counts as correct when the input is ambiguous, missing or inconsistent. Keep abstentions visible rather than dropping them from the denominator.
A human clicking approve is not automatically that label. They may miss an error or accept a useful draft that still needs repair. Collect outcome judgments deliberately and keep their provenance.
Calibration is a relationship across cases
For predictions near 0.8, calibration asks whether about 80% are correct across the relevant cases. It does not certify the next individual prediction. Guo, Pleiss, Sun and Weinberger studied calibration in classification networks in On Calibration of Modern Neural Networks. Their results are a foundation, not validation of a particular LLM’s self-reported score.
Illustrative example. Invented teaching example: 20 cases per bin, with 9, 10, 11, 13 and 14 correct answers. Not a model benchmark. Small bins have substantial sampling uncertainty.
View data table
| Category | Perfect calibration reference | Synthetic observed correctness |
|---|---|---|
| 0.50 | 50 | 45 |
| 0.60 | 60 | 50 |
| 0.70 | 70 | 55 |
| 0.80 | 80 | 65 |
| 0.90 | 90 | 70 |
In this invented example, the highest bin is labelled 0.9 but only 14 of its 20 answers are correct. The gap is the lesson, not the exact size. A real report needs sample counts, the evaluation population and uncertainty estimates alongside the curve.
Keep tuning away from the final test
Use one set of cases to develop the score and fit any calibration method, then evaluate on held-out cases. Include enough difficult and recent examples to notice where the score fails. Report results by important task type rather than letting abundant easy requests hide rare expensive mistakes.
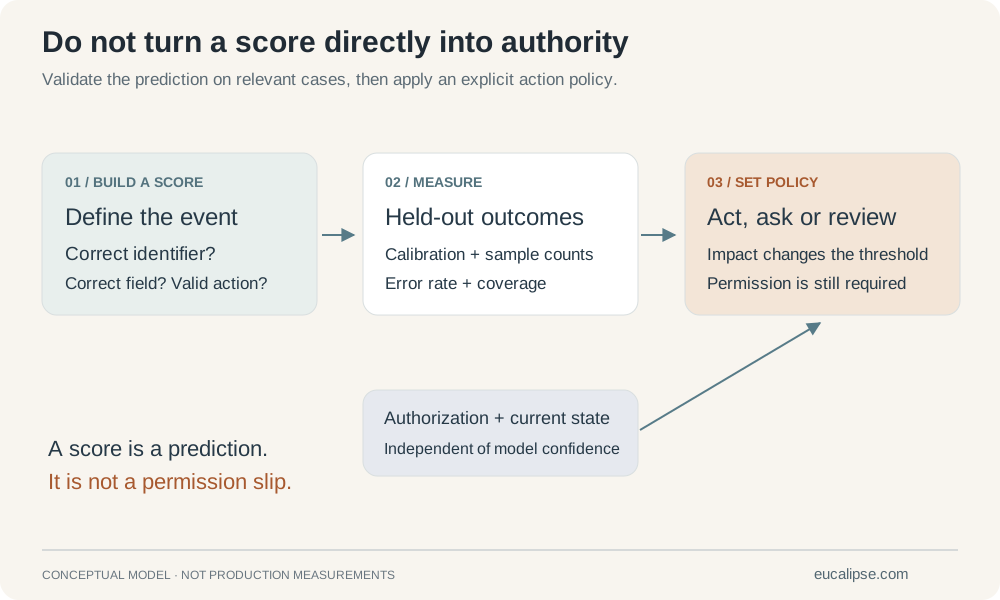
Measure accuracy on the selected cases together with coverage: how much traffic the system accepts. A threshold that accepts almost nothing can look impressive while being operationally useless. Recheck after model, prompt or retrieval changes and watch for changes in the input population.
Let impact shape the threshold
A plausible match might be enough to suggest a search result. It may be insufficient to modify a sensitive record. Missing permissions, stale data and an irreversible effect remain reasons to block even when a score is high. Confidence does not waive these checks.
Choose thresholds against a stated error budget and the cost of review. There is no universal “0.9 means execute” rule. For a new workflow without reliable calibration evidence, it can be more honest to display “needs review” and the conflicting evidence than a percentage.
Make the interface help people check
Show the relevant source and the uncertainty that changes the decision. “Two supplier records share this name” is more actionable than “confidence 71%.” If you display a score, explain what event it predicts and avoid precision that the evaluation cannot support.
The examples in Evals that grow themselves connect reviewed cases back to testing. Keep that loop, but distinguish accepted work from independently checked labels. The score earns trust through those checks, not through the number of decimal places in the interface.
Frequently asked questions
Is an LLM’s stated confidence a calibrated probability?+
Not automatically. It needs evaluation against defined outcomes on relevant held-out cases before it can be interpreted that way.
Can a calibrated score authorize an action?+
No. Authorization, current state and impact are separate checks. Calibration describes prediction behavior across cases.
Are the plotted values measured results?+
No. They are a labelled synthetic teaching example with 20 invented cases per bin.
Let's Talk About Your Project
Have questions about nearshoring or AI development? Our team is here to help you make the right decision.
- ✓Free consultation on your AI project
- ✓Custom cost estimates and timeline
- ✓Access to nearshore talent pools